The Storage Question Every RAG Feature Runs Into
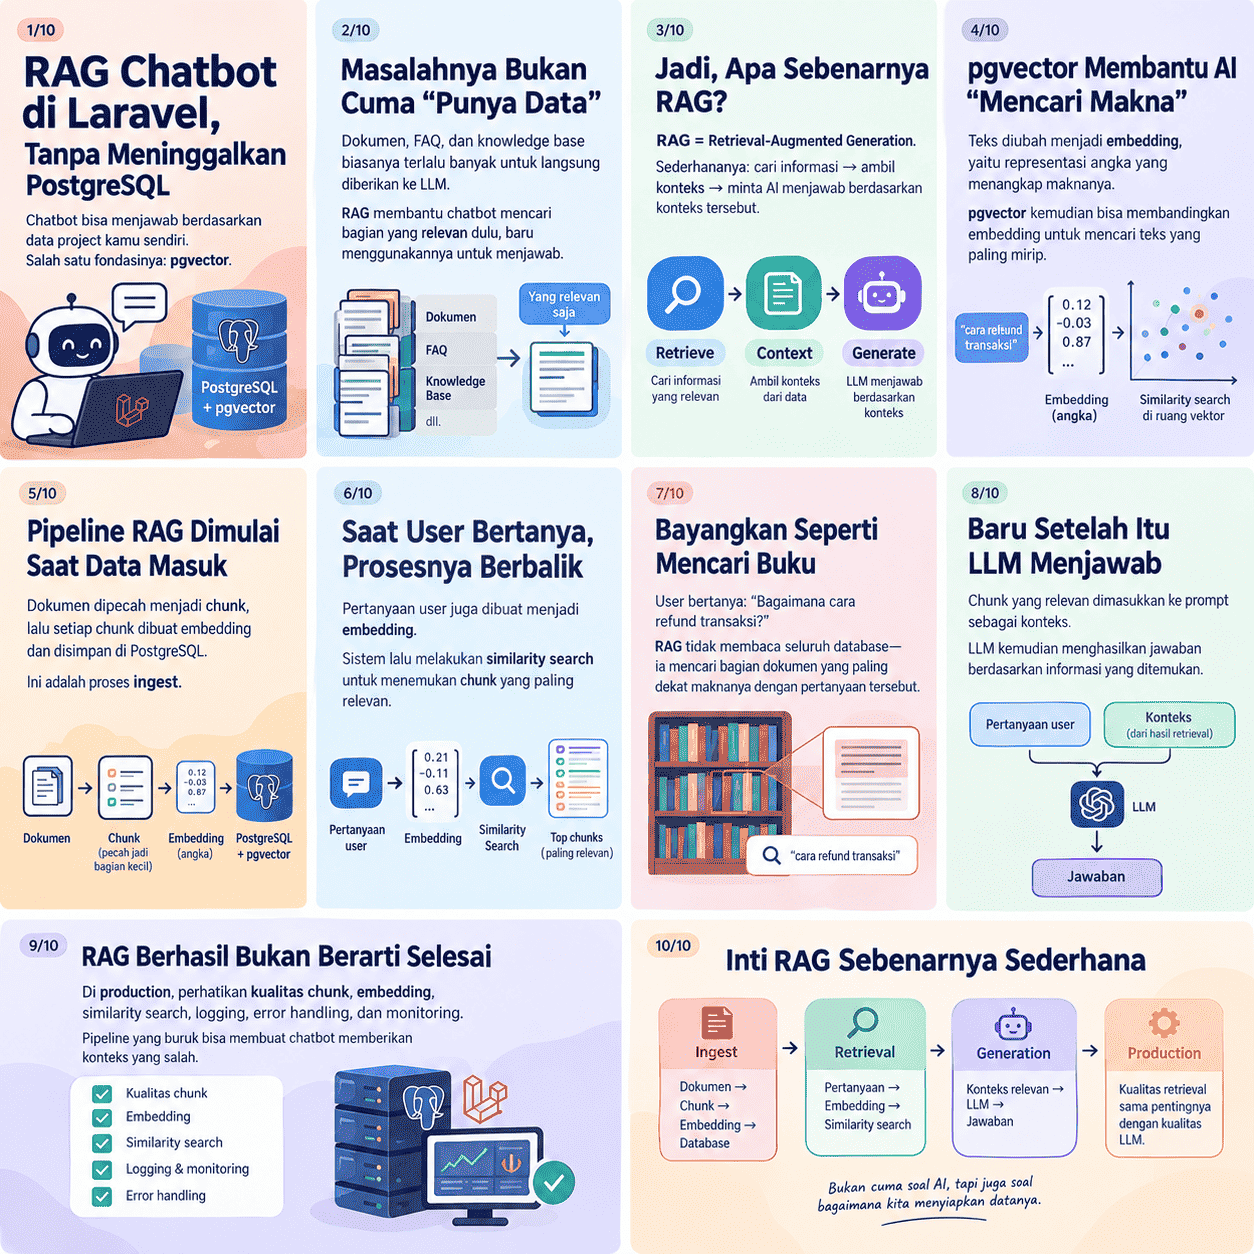
The chunker is written, the embedding model is chosen, and your Retrieval-Augmented Generation (RAG) pipeline is taking shape. Then the classic question arrives: where do the vectors live? The reflex for many teams is to add a dedicated vector database next to the PostgreSQL instance they already run. Yet for most real-world workloads, such as documentation search, internal knowledge bases, or support ticket classification, PostgreSQL with the pgvector extension is more than enough.
Before choosing storage, ask a more basic question: do you need retrieval at all? Anthropic notes that if your knowledge base is smaller than roughly 200,000 tokens (about 500 pages), you can place the whole thing in the prompt, especially with prompt caching cutting latency and cost substantially. This article is for the case where your data has already outgrown that.
What You Give Up by Adding a Separate Service
Adding a vector database is not just one more dependency. It is one more distributed system, with everything that implies:
- A sync pipeline. Documents live in Postgres, embeddings live somewhere else. Every insert, update, and delete has to land in two places. When one write fails, you end up with a document that has no embedding or an orphaned vector pointing at a deleted document. The fix is usually intricate retry logic or a background reconciliation job.
- Extra credentials. Another secret to store, rotate, and scope, plus per-service connection handling and retry configuration.
- Extra deploys and monitoring. Another dashboard, another alert policy, and another component that can fail independently of your application.
- Weaker consistency. The relationship between application data and the search index shifts from transactional to eventual.
The promised performance gain often goes unnoticed by users. According to Encore, the vector search step typically takes 5–50 ms, the embedding API call 100–300 ms, and LLM generation anywhere from 500 ms to 3 seconds. The gap between a 2 ms and a 10 ms search is invisible next to that.
| Aspect | Dedicated Vector DB | Postgres + pgvector |
|---|---|---|
| Services involved | 3 (Postgres, vector DB, embedding API) | 2 (Postgres, embedding API) |
| Sync required | Yes | No |
| Consistency | Eventual | Transactional |
| Failure modes | Orphaned vectors, stale embeddings | Standard Postgres failures |
pgvector in Practice
pgvector adds a vector column type, distance operators, and approximate nearest neighbor indexes directly to Postgres. A simple RAG schema might look like this:
CREATE EXTENSION IF NOT EXISTS vector;

CREATE TABLE documents (
  id bigserial PRIMARY KEY,
  tenant_id bigint NOT NULL,
  title text NOT NULL,
  status text NOT NULL DEFAULT 'draft',
  updated_at timestamptz NOT NULL DEFAULT now()
);

CREATE TABLE chunks (
  id bigserial PRIMARY KEY,
  document_id bigint NOT NULL REFERENCES documents(id) ON DELETE CASCADE,
  content text NOT NULL,
  embedding_model text NOT NULL,
  embedding vector(1536) NOT NULL
);
The available distance operators:
| Operator | Distance | Notes |
|---|---|---|
<-> |
L2 (Euclidean) | Default in many examples |
<#> |
Negative inner product | Negated because Postgres only supports ASC index scans on operators |
<=> |
Cosine | Similarity = 1 - (a <=> b) |
<+> |
L1 (taxicab) | Since 0.7.0 |
<~> / <%> |
Hamming / Jaccard | For binary vectors |
Here is where it shines: metadata filters, joins, and similarity search all run in a single SQL query.
SELECT c.id, c.content, d.title,
       1 - (c.embedding <=> $1) AS similarity
FROM chunks c
JOIN documents d ON d.id = c.document_id
WHERE d.tenant_id = $2 AND d.status = 'published'
ORDER BY c.embedding <=> $1
LIMIT 20;
For the index to be used, the query needs an ORDER BY on a distance operator in ascending order plus a LIMIT. Writing ORDER BY 1 - (embedding <=> $1) DESC makes the planner skip the index.
There is a bonus, too. Anthropic's Contextual Retrieval research found that combining embeddings with lexical search (BM25) beats embeddings alone. Contextual embeddings plus contextual BM25 cut top-20 retrieval failures by 49%, and by 67% once reranking was added. In Postgres, built-in full-text search can fill that lexical role (it is not an identical BM25 implementation, but it serves the same purpose), with the result lists merged via Reciprocal Rank Fusion. All of it stays in one database.
Index Choice: Exact, IVFFlat, or HNSW
By default pgvector performs exact search, which gives perfect recall. Approximate indexes trade some recall for speed, and query results can change once you add one.
| Index | Recall | Build & Memory | Key Parameters |
|---|---|---|---|
| Exact (no index) | 100% | No index cost, but a linear scan | max_parallel_workers_per_gather |
| IVFFlat | Lower at the same speed | Fast build, smaller footprint | lists, ivfflat.probes (default 1) |
| HNSW | Best speed-recall trade-off | Slower build, more memory | m=16, ef_construction=64, hnsw.ef_search=40 |
IVFFlat splits vectors into lists and scans only the closest ones. Build it after the table has data, start with lists = rows/1000 up to 1M rows and sqrt(rows) beyond that, and set probes to roughly sqrt(lists).
HNSW builds a multilayer graph. There is no training step, so it can be created on an empty table. Builds are much faster when the graph fits in maintenance_work_mem.
CREATE INDEX CONCURRENTLY ON chunks USING hnsw (embedding vector_cosine_ops);
Do the memory math. Each vector takes 4 * dimensions + 8 bytes, so a 1,536-dimension vector needs 6,152 bytes. A million chunks means around 6.2 GB of raw vector data before any index. halfvec halves that to 3,080 bytes, and binary quantization brings it down to about 200 bytes per vector (with re-ranking against the original vectors to recover recall). Mind the index limits as well: vector can only be indexed up to 2,000 dimensions and halfvec up to 4,000, so a 3,072-dimension model needs a halfvec expression index.
A commonly missed trap: with approximate indexes, the WHERE filter is applied after the index is scanned. If a condition matches 10% of rows and ef_search is at its default of 40, only about 4 rows survive on average. The fixes are iterative index scans (since 0.8.0) via SET hnsw.iterative_scan = strict_order, partial indexes when filtering on a few distinct values, or LIST partitioning per tenant for multi-tenant isolation. Monitor recall regularly by comparing approximate results with exact search using SET LOCAL enable_indexscan = off.
Scale Thresholds: When a Dedicated Vector Database Pays Off
The table below combines figures from the sources with practical heuristics. Treat the boundaries as guidance, not law.
| Size/Condition | Recommendation |
|---|---|
| Knowledge base under ~200K tokens | Put it in the prompt with prompt caching, skip RAG |
| Thousands to tens of thousands of vectors | pgvector, exact search is fine |
| Hundreds of thousands to a few million vectors | pgvector + HNSW (benchmarks cited by Encore: under 20 ms at 1M vectors with recall above 95%) |
| Tens of millions of vectors | Still workable in pgvector with halfvec, binary quantization, partitioning, replicas, or sharding (Citus, PgDog), but tuning costs start to bite |
| Billions of vectors, extreme write throughput, per-tenant isolation at scale, zero-tuning autoscaling | A dedicated vector database genuinely starts to pay off |
The real signal to move is not raw row count. It is when your HNSW index no longer fits in a reasonably sized server's memory, when index rebuilds and vacuuming start disrupting operations, or when multi-tenant filtering drags recall down and partitions become unmanageable.
Keeping Documents and Embeddings Consistent in One Transaction
This is pgvector's biggest advantage: a document and its embeddings can be written in a single ACID transaction. Search queries never see a half-finished state. The pattern:
- Compute embeddings outside the transaction. An embedding API call takes hundreds of milliseconds, and holding a transaction open across a network call keeps rows locked for far too long.
- Open the transaction, save the document, delete the old chunks, and insert the new chunks with their embeddings.
- Commit. If any step fails, everything rolls back.
In Laravel:
// Network call happens before the transaction opens
$vectors = $embedder->embedMany($chunks);

DB::transaction(function () use ($doc, $chunks, $vectors) {
    $doc->save();
    DB::table('chunks')->where('document_id', $doc->id)->delete();

    foreach ($chunks as $i => $chunk) {
        DB::table('chunks')->insert([
            'document_id' => $doc->id,
            'content' => $chunk,
            'embedding_model' => 'text-embedding-3-small',
            'embedding' => '[' . implode(',', $vectors[$i]) . ']',
        ]);
    }
});
A few details that will save you in production: store the model name in an embedding_model column so you can migrate to a new model gradually; store a content hash so unchanged text skips re-embedding; and if two updates can race, check a version or updated_at inside the transaction so embeddings computed from stale content never overwrite newer ones. Thanks to ON DELETE CASCADE, deleting a document removes all of its vectors automatically, so orphans simply cannot exist.
Conclusion
For backend engineers designing the storage layer of an AI feature, the most rational starting point is the Postgres you already run. pgvector gives you distance operators, HNSW and IVFFlat indexes, filtering in the same SQL statement, hybrid search alongside full-text search, and above all, transactional consistency without a sync pipeline. Dedicated vector databases have their place at billions of vectors and extreme write loads. Move when your metrics demand it, not out of architectural reflex. Need help provisioning a Postgres server with pgvector or building AI features into your website? The katili.dev team is ready to help.